General Thai Document OCR
Reads a printed Thai or English document and returns its text, its layout, or a Word, PowerPoint, Excel or searchable PDF file made from it.
Since 5 October 2026 the pages are read by iApp's own Thai OCR model. On Thai documents it returns more accurate text than Google Cloud Vision (measured), and plain text costs 0.049 IC per page, down from 1 IC.
- Price0.049 ICper page
- Measured96.3%
- Capacity27,000 pages/hour
- Served418Kcalls
Input
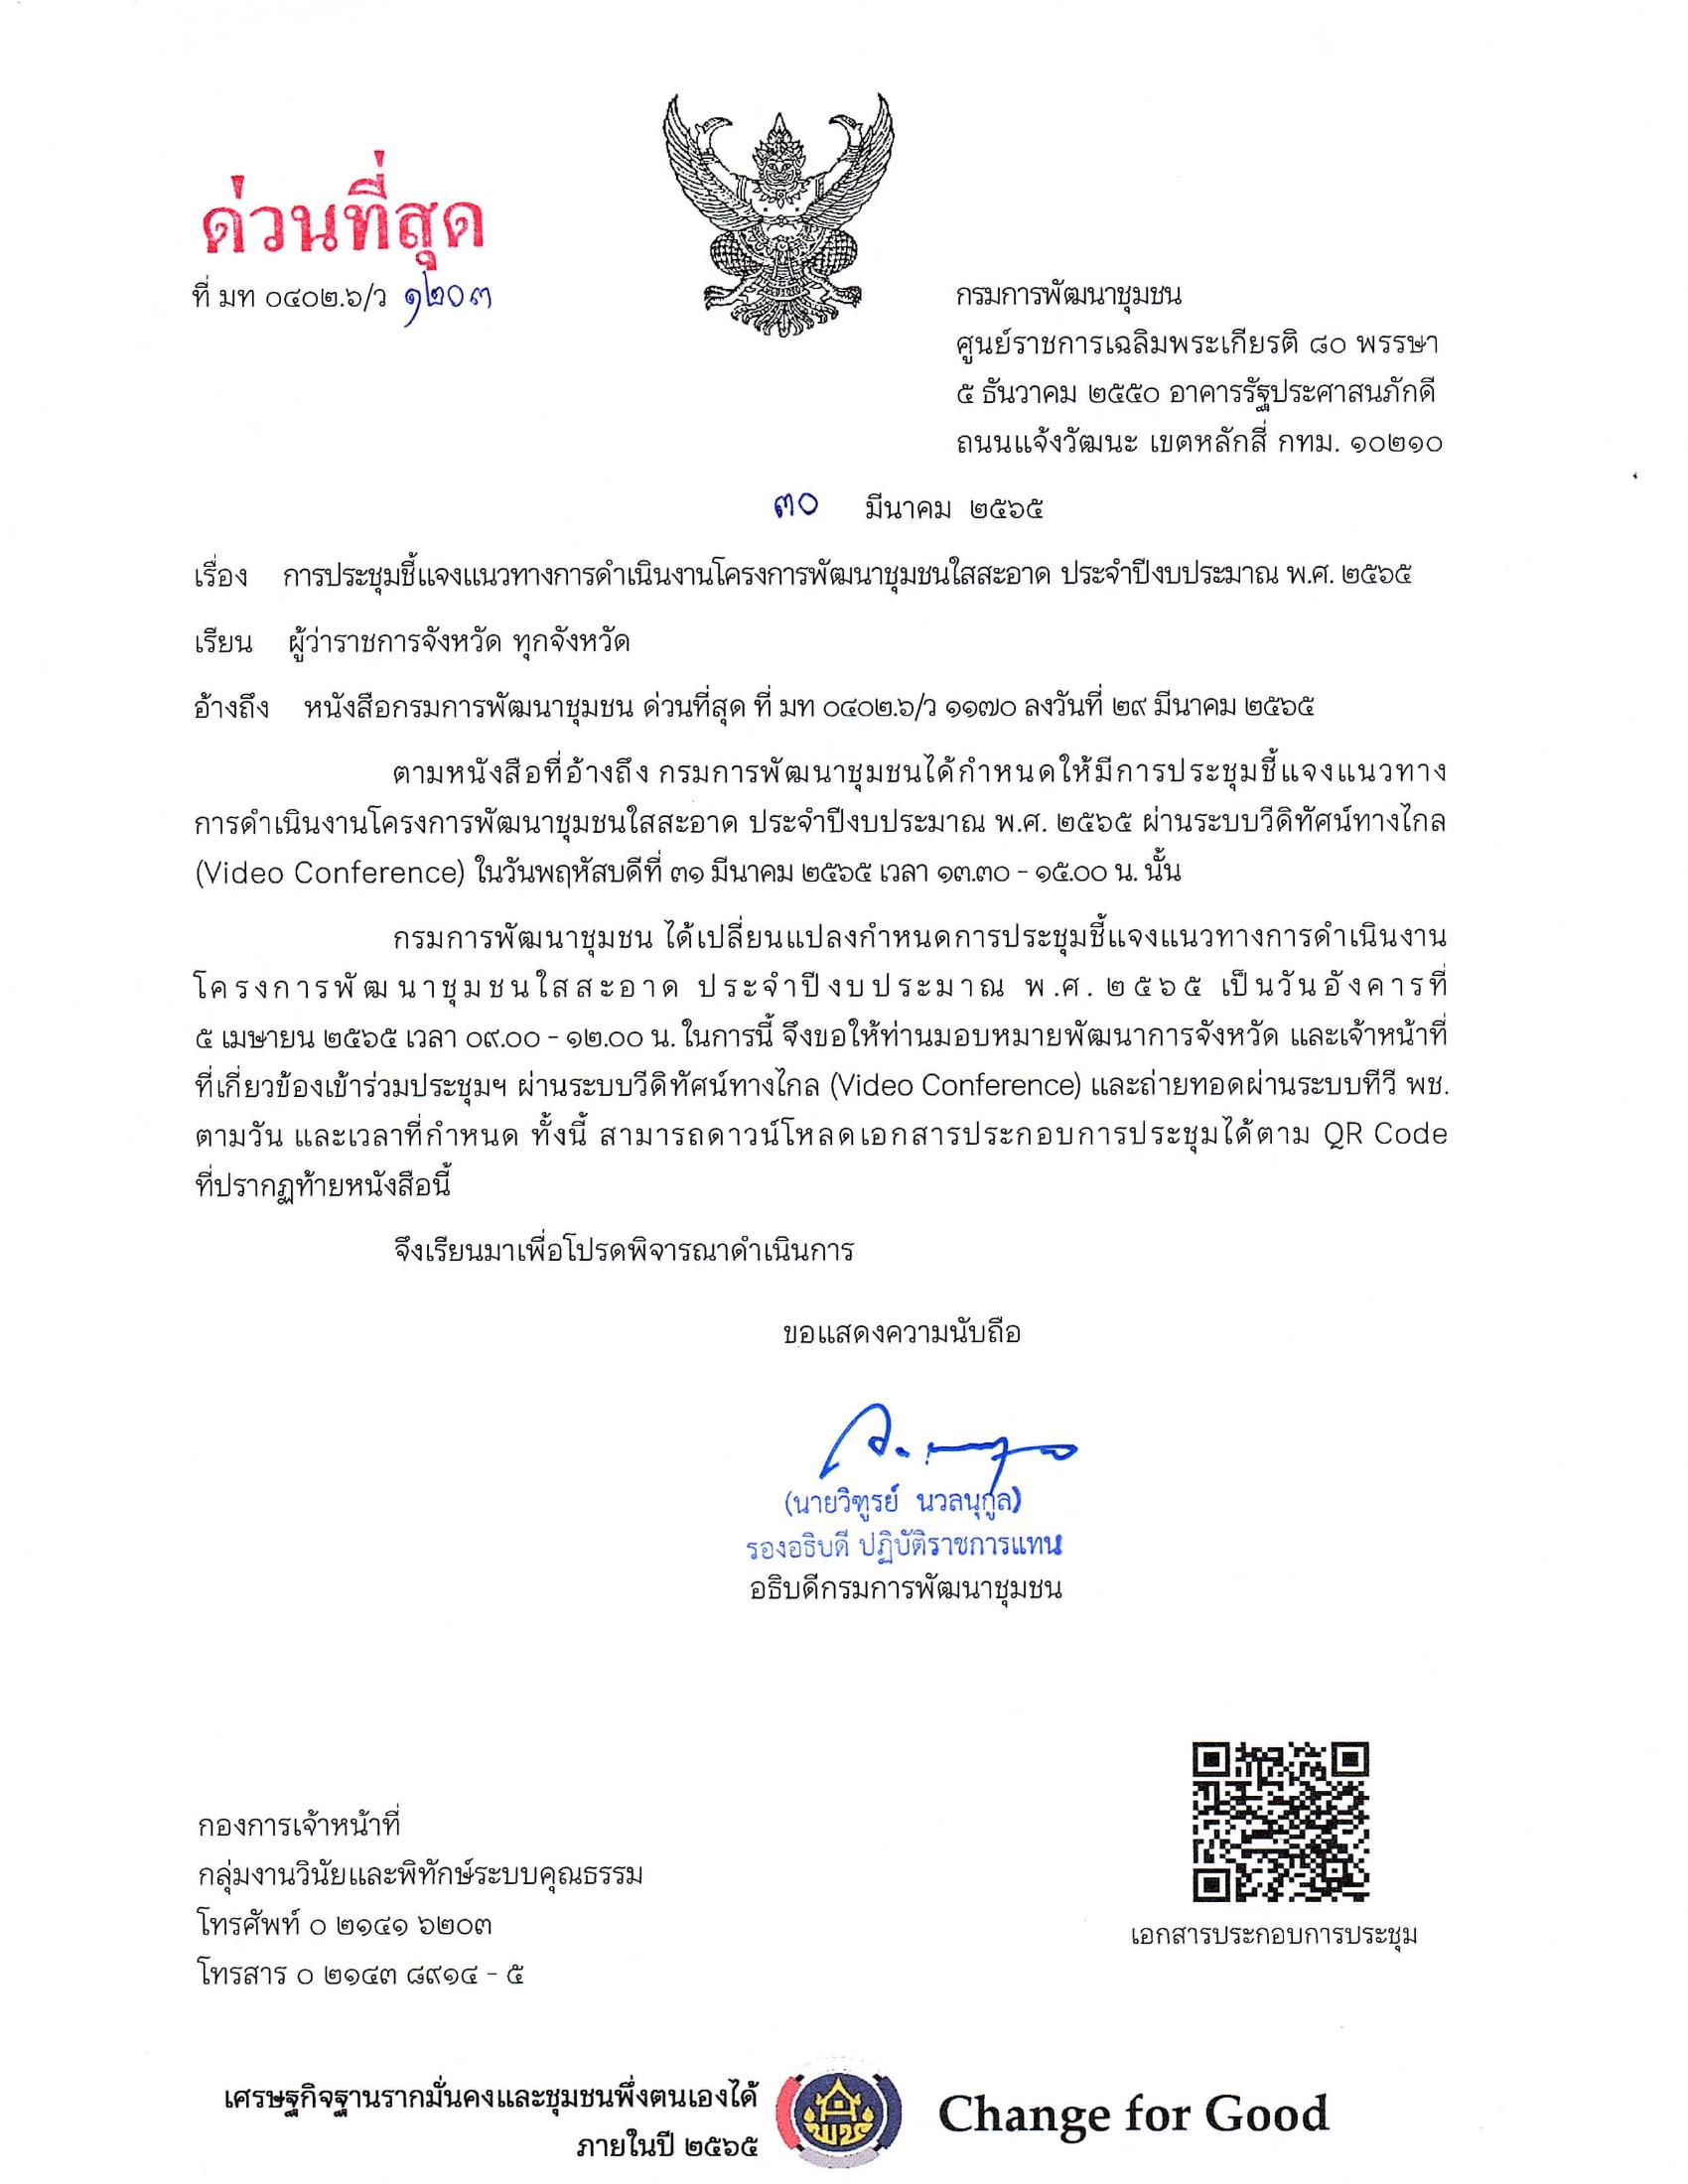
OutputPOST /v3/store/ocr/document/ocr
- text
- ด่วนที่สุด ที่ มท ๐๔๐๒.๖ ...
- time
- 0.6
- iapp
- page: 1 char: 1376
The text is shown in part; the page has 1,376 characters.
Every field, under ResponseOther endpoints: /layout, /docx, /pptx, /xlsx, /searchablePDF see Request
Request
multipart/form-data. Every endpoint takes the same fields; pick one by the output you want. Plain text costs 0.049 IC per page; layout, Word, PowerPoint, Excel and searchable PDF cost 0.15 IC per page.
Headers
apikeystringrequiredBody
filefilerequiredbase64 is sent.base64stringfile.emailstring| Endpoint | Returns | Per page |
|---|---|---|
/v3/store/ocr/document/ocr | Plain text, one string per page | 0.049 IC |
/v3/store/ocr/document/layout | JSON: every component with its text, bounding box and type | 0.15 IC |
/v3/store/ocr/document/docx | A link to a generated Word file | 0.15 IC |
/v3/store/ocr/document/pptx | A link to a generated PowerPoint file | 0.15 IC |
/v3/store/ocr/document/xlsx | A link to a generated Excel file | 0.15 IC |
/v3/store/ocr/document/searchablePDF | A link to the original pages with a selectable text layer | 0.15 IC |
The same endpoints answer under the legacy /document-ocr prefix.
Response
JSON, one shape per endpoint. The header iapp-input-pages carries the number of pages read; the charge is that number times the endpoint's price per page.
The 38 component types
| Group | Types |
|---|---|
| Titles and body | CenTitle, Para1 to Para5, BodyText3, Text, TextBox |
| Lists | List, ListNum1 to ListNum4, ListCon1 to ListCon4 |
| Indented blocks | Indent1 to Indent5 |
| Tables | Table, TableLike |
| Page furniture | Header, Footer, Date, NextPage, UpperLeft, UpperRight, TopRight, BottomLeft, BottomRight |
| Graphics | Figure, Logo, LeftLogo |
| Signatures | Signature |
Details
Measured
Compared with Google Cloud Vision on 4 October 2026: the same page images and the same checked answers for both, scored by character error rate (lower is better). None of these documents was used to train the model.
| Thai documents | Google Cloud Vision | iApp | Better on: iApp / Google |
|---|---|---|---|
| Budget documents, parliament (539 pages) | 37.4% | 17.2% | 469 / 25 pages |
| Royal Gazette (221 pages) | 13.8% | 6.1% | 217 / 0 pages |
| SEA-DocBench, Thai (1,225 pages) | 49.4% | 48.7% | 443 / 243 pages |
| Old books, Wikisource (608 pages) | 25.4% | 21.0% | 413 / 124 pages |
| Administrative Court judgments, scanned (150 documents) | 6.2% | 3.1% | 150 / 0 documents |
| All 2,825 benchmark pages | 36.0% | 29.6% | 1,654 / 425 pages |
The court judgments are within the model's training domain: it was trained on other judgments of the same court, never on these. The gap is widest on government documents: Google reads a two-column budget table as all the labels and then all the amounts, so each amount loses its line item, while iApp reads it row by row and its text can be used as it is.
The court benchmark of the August whitepaper (20 judgments, 242 pages, the same script and scoring), re-run on the production service on 5 October 2026:
| Measure | v3.0.0, Oct 2026 | v2.1.13, Aug 2026 | Google Cloud Vision |
|---|---|---|---|
| Character error rate | 3.7% (96.3% correct) | 5.2% (94.8%) | 6.1% (93.9%) |
| Word error rate | 5.6% (94.4% correct) | 7.0% (93.0%) | 7.5% (92.5%) |
| Layout analysis | 96.97% AP, the same layout model | 96.97% AP |
Measured on the production service in October 2026: a median of 0.60 s per page of plain text; about 7.5 pages a second (27,000 an hour) for plain text, and about 0.6 pages a second (2,100 an hour) for layout, Word, PowerPoint and Excel. The service runs on two servers and stays up if one fails.
Method, every set with its confidence interval, and the per-document results: the benchmark paper (PDF)
Limits
- Printed text only; handwriting is not read.
- Scans at 200 dpi or higher give the best results.
- Short photographed text, such as signs and scene text, is read, but Google Cloud Vision was slightly more accurate on it in our tests.
Data handling
Uploaded documents are processed on iApp servers in Thailand and used only to produce the requested output; generated links expire after 10 minutes and generated files are deleted within one hour. The service is GDPR and PDPA compliant. An on-premise deployment, in which no document leaves your network, is available: contact us.
Changelog
| Version | Date | Changes |
|---|---|---|
| v3.0.0-20261005 | 5 Oct 2026 | iApp's own Thai OCR model reads the pages; on Thai documents it is more accurate than Google Cloud Vision (measured), and the character error rate on the August benchmark falls from 5.2% to 3.7%. The service runs on two servers: about 27,000 pages an hour, no downtime on deploys. Plain text from 1 IC to 0.049 IC per page; layout, Word, PowerPoint, Excel and searchable PDF from 1 IC to 0.15 IC per page. Endpoints, requests and responses are unchanged. |
| v2.1.13-20260822 | 22 Aug 2026 | New engine (character error rate down 15% relative, median page time from 3.33 s to 0.53 s), signed expiring file links, on-premise deployment, and PowerPoint, Excel and searchable PDF out of preview. Benchmark paper (PDF) |
| v2.1.12-20251116 | 16 Nov 2025 | Added the iapp-input-pages response header. |
| v2.0 | Aug 2022 | Document layout analysis and Word output. |